The Morning After the Fifth House
Yesterday, in Chapter 001, you taught a machine something.
Four houses had sold:
| Rooms | Sold for (₹ lakh) |
|---|
| 1 | 3 |
| 2 | 5 |
| 3 | 7 |
| 4 | 9 |
The machine discovered the compact rule y^=wx+b.
Training pushed the two dials close to w=2 and b=1, so the machine learned y^=2x+1.
Five rooms? y^=2(5)+1=11.
Meera was happy.
Ramesh was suspicious.
You went home feeling that machine learning might actually make sense.
Then the next morning arrives.
Meera puts two files on your desk.
Both houses have three rooms.
One is a compact 800-square-foot flat facing the road.
The other is a 1,600-square-foot flat facing a park.
They did not sell for the same price.
You already know what your model will do.
For both houses, x=3.
Therefore, for both houses, y^=2(3)+1=7.
Same input.
Same prediction.
Every time.
Meera looks at you.
“The houses are different. Why does the machine think they are the same?”
That question is the beginning of linear algebra.
The Model Is Not Stupid. It Is Blind.
The problem is not gradient descent.
It is not the learning rate.
It is not that you need more training.
No amount of training can fix this:
xsmall flat=3,xlarge flat=3.
The machine receives the same number for both houses.
So any rule of the form y^=f(x) must give the same answer to both.
The missing information is sitting right in the files:
- number of rooms,
- floor area,
- perhaps age,
- perhaps floor number,
- perhaps distance from the station.
But your model sees only one of them.
The failure is not in learning. The failure is in representation.
The world contains more information than the input can currently hold.
Chapter 001 taught us how a machine can learn a rule.
Chapter 005 asks a more basic question:
What exactly are we going to give the machine as its input?
The First New Word: Feature
A feature is one measurable or encoded fact that we allow the machine to see.
For a house:
| Feature | Example value |
|---|
| rooms | 3 |
| area | 800 sq ft |
| age | 6 years |
| floor | 4 |
| distance to station | 1.2 km |
Yesterday, the model had one feature: x=rooms.
Now we want at least two: x1=rooms and x2=area.
For the smaller flat, x1=3 and x2=800.
For the larger flat, x1=3 and x2=1600.
At last the machine can see that they are different.
But we have created a new problem.
Yesterday the input was one thing: x.
Today the input is becoming x1,x2,x3,…
A photograph may have thousands or millions of measurements.
A language model may represent one token using thousands of learned numbers.
Are we really going to carry them around one by one?
We need a single mathematical object that can hold many numbers without crushing them together.
🧑💼 Ramesh’s First Fix — “Just Add Them”
Ramesh has been waiting for this moment.
“Easy,” he says. “You still want one input. Make one input.”
For a two-room, 800-square-foot house, his score is 2+800=802.
Problem solved.
Except it is not.
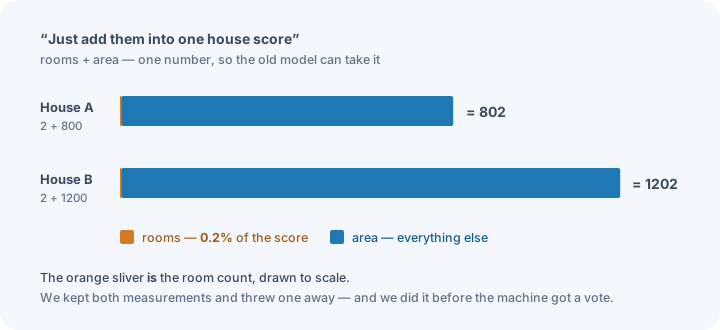
What does the number 802 mean?
Is one room worth one square foot?
According to this encoding, yes.
If the house gains one room, the score changes 802→803.
If the house gains one square foot, the score also changes 802→803.
The two completely different changes become identical.
Worse, area is numerically hundreds of times larger than room count. The smaller feature almost disappears inside the larger one.
A Tempting Wrong Idea
“If the model accepts one number, compress all the features into one number.”
The compression silently decides how the features should be combined before the machine gets a chance to learn that combination.
The whole point of learning is to let the machine discover how much each feature should matter.
So the features must travel together while remaining separate.
What Would a Real Representation Need?
Before inventing the solution, write down what it must do.
A useful representation should:
- Hold several features together as one mathematical object.
- Keep their identities separate. Rooms must not blur into area.
- Preserve order. Slot 1 cannot mean rooms today and age tomorrow.
- Scale to many features. Two features now; thousands later.
- Work with arithmetic. We should be able to add changes, scale them, compare them, and eventually learn with them.
That list forces the next idea into existence.
🔍 The Discovery — Put the Features in One Ordered Box
Instead of carrying two separate symbols, x1=3 and x2=800, put them together:
x=[3800].
This is a vector.
Read it as:
x=[roomsarea].
For the compact flat:
xA=[3800].
For the larger flat:
xB=[31600].
Same room count.
Different vector.
The machine can finally tell the two houses apart.
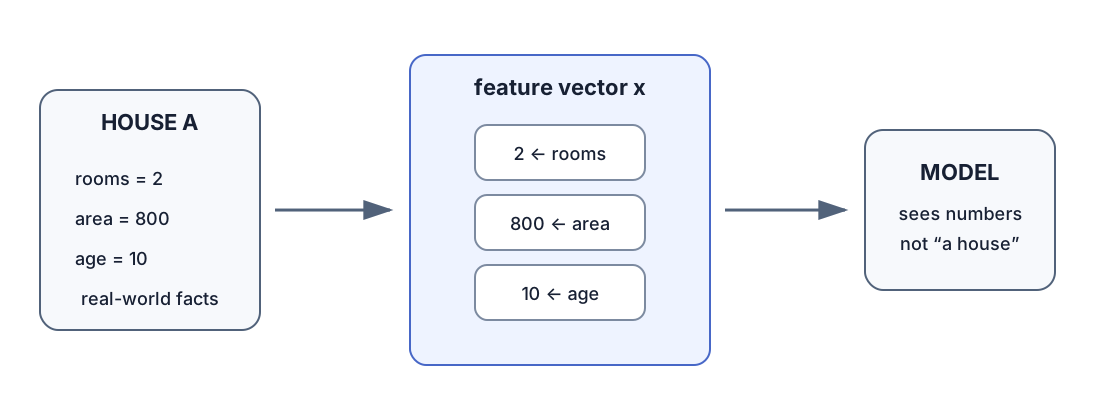
The vector is not the house.
It is not even everything we know about the house.
It is the numerical description we chose to give the machine.
That distinction matters.
Mental model
A feature is one fact.
A feature vector is the collection of facts the machine sees about one example.
The Smallest Important Change From Chapter 001
Yesterday: x=3.
One input number.
Today:
x=[3800].
Several input numbers.
That is the entire conceptual jump.
A scalar became a vector.
We usually write scalars with ordinary letters such as x, y, w, and b.
We usually write vectors in bold, such as x, w, and v.
The boldface is not decoration.
It tells your brain:
“This symbol contains several coordinates.”
If the vector contains d features, we write x∈Rd.
Do not let that notation sound grander than it is.
It simply means:
x contains d real numbers.
For our two-feature house, x∈R2.
For a 784-pixel image flattened into one list, x∈R784.
Same idea.
More slots.
The Order Is Part of the Meaning
Suppose we agree that
x=[roomsarea].
Then
[3800]
means three rooms and 800 square feet.
But
[8003]
does not mean the same thing.
The numbers are the same.
The meaning is different because the slots changed.
A vector is an ordered collection.
Think of a school bag with labelled pockets.
You may change what is inside a pocket.
You may not randomly change what the pocket means.
That rule becomes extremely important later when vectors have thousands of coordinates.
From a List of Numbers to a Point in Space
So far a vector is useful bookkeeping.
Now comes the reason linear algebra becomes visual.
Take a simpler vector:
x=[28].
Suppose the first coordinate is rooms and the second is area measured in hundreds of square feet.
We can draw those two numbers as the point (2,8).
Two coordinates become one location.
And if we draw an arrow from the origin to that point, the same vector becomes an arrow.
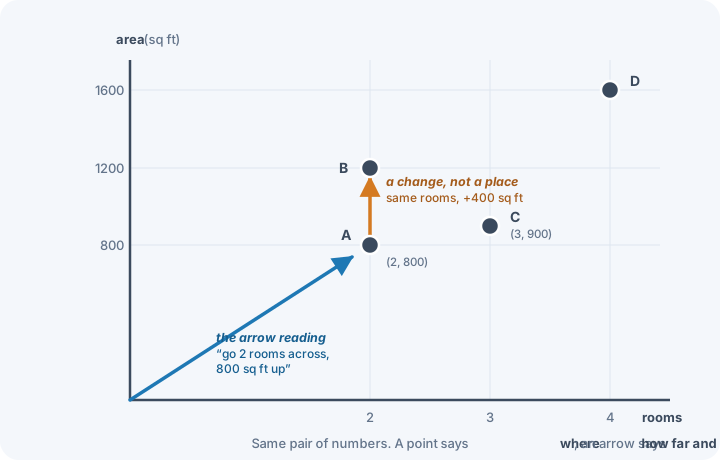
So one vector now has three readings:
| View | What x means |
|---|
| Data | the features describing one house |
| Point | where that house sits in feature space |
| Arrow | a direction and amount from the origin |
Nothing changed in the numbers.
Only our interpretation changed.
This is the first deep idea of linear algebra:
Numbers can become geometry.
That is why this level exists.
Why the Arrow Picture Is More Than Decoration
Suppose a house currently has
x=[2800].
Now the owner adds one room and 200 square feet.
That change is
Δx=[1200].
The new house is
xnew=x+Δx.
Numerically,
[2800]+[1200]=[31000].
Geometrically, vector addition means: walk one arrow, then continue with the other.
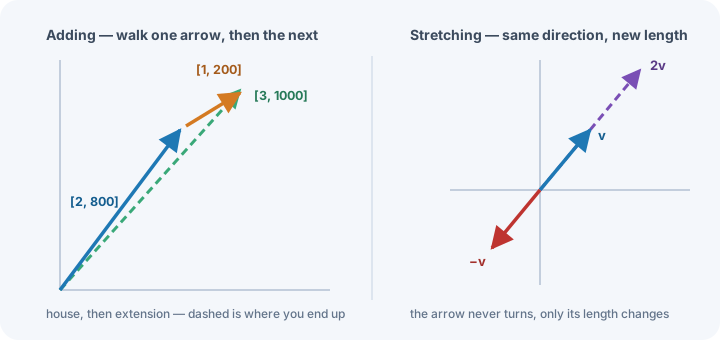
Now suppose we double the change:
2Δx=2[1200]=[2400].
Multiplying a vector by one number stretches every coordinate by the same factor.
That number is called a scalar.
So we have two basic moves: vector addition, u+v, and scalar multiplication, cu.
Add vectors.
Scale vectors.
Those two moves look almost too simple to deserve names.
But Chapter 006 will ask what entire spaces can be built using nothing but those two operations.
The House Still Needs a Price
We have solved the representation problem.
We have not solved the prediction problem.
The machine now sees
x=[roomsarea],
but Chapter 001 taught us that a model needs adjustable dials.
Yesterday there was one input feature, so there was one main weight: y^=wx+b.
If there are two input features, each needs its own weight:
y^=w1x1+w2x2+b.
For house pricing, we can read that as
y^=wroomsxrooms+wareaxarea+b.
One dial controls how much room count matters.
Another controls how much area matters.
The bias still shifts the whole prediction.
Nothing from Chapter 001 was discarded.
We simply gave the model more information and therefore more dials.
A Small Numerical Example
Take
xA=[3800].
Choose, just for illustration,
wrooms=1,warea=0.005,b=0.
Then
y^A=1(3)+0.005(800)=3+4=7.
Now use the larger flat:
xB=[31600].
The same rule gives
y^B=1(3)+0.005(1600)=3+8=11.
The two houses have the same room count.
But area has its own weight, so the model can finally give different predictions.
This is exactly what the one-number model could not do.
What the Weights Really Mean
Notice the units.
If price is measured in lakh rupees, then wrooms has units of roomlakh, while warea has units of square footlakh.
The weights are allowed to be very different numbers because the features mean different things.
That is why Ramesh’s “just add the features” trick was wrong.
He combined the measurements before giving the machine a chance to learn separate weights.
A useful mental model is:
The feature vector says what the example contains.
The weight vector says how strongly the model currently cares about each feature.
So let us put the weights into a vector too.
w=[w1w2].
Now both sides of the model have the same shape:
x=[x1x2],w=[w1w2].
One feature.
One matching weight.
Slot by slot.
🔍 The Next Compression — Pair, Multiply, Add
The prediction still looks like this:
y^=w1x1+w2x2+b.
With five features:
y^=w1x1+w2x2+w3x3+w4x4+w5x5+b.
With a million:
y^=w1x1+w2x2+⋯+w1000000x1000000+b.
The idea is simple.
The notation is becoming ridiculous.
Look at the repeated instruction:
- pair each feature with its weight,
- multiply each pair,
- add the products.
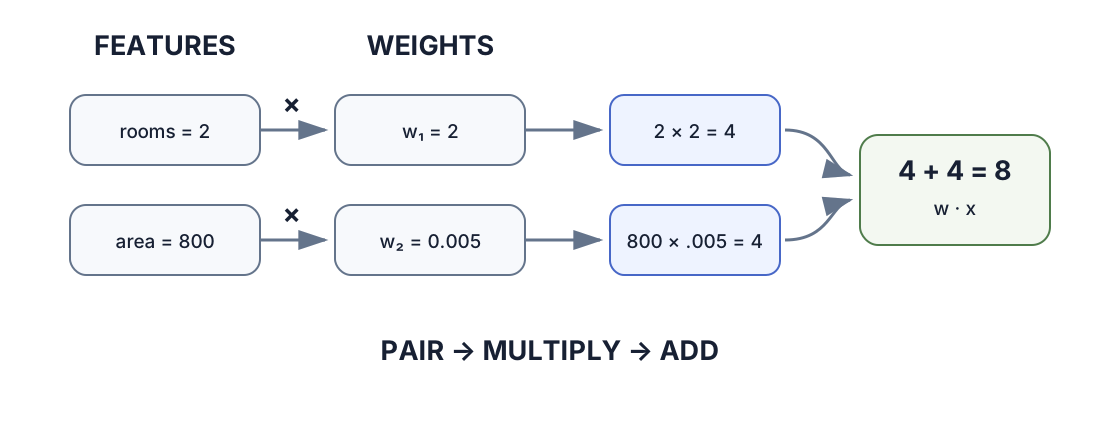
Mathematics gives that repeated operation a name:
dot product.
We write
w⋅x=i=1∑dwixi.
So the whole model becomes
y^=w⋅x+b
That is Chapter 001’s model grown up.
When d=1, w⋅x=wx, so we recover y^=wx+b.
When d=2, w⋅x=w1x1+w2x2.
When d=1000000, the notation does not change.
Only the number of coordinates changes.
Mental model
When you see
w⋅x,
hear:
pair, multiply, add.
That is all we need from the dot product today.
Chapter 007 will return to it and ask a much deeper question:
Why does this same arithmetic also measure how two directions align?
Do not steal that discovery from future-you.
This Is Already the Beginning of a Neuron
There is one connection worth seeing now.
A basic artificial neuron begins with z=w⋅x+b.
That is the same weighted sum we just built.
Later the neuron applies another function to z, called an activation function.
For now, stop before that step.
The important connection is simply this:
The arithmetic inside a neuron starts with the same feature-vector and weight-vector story we just discovered from house prices.
Deep learning did not invent a completely different mathematics.
It builds on this one.
Shapes — Start Reading Them Now
Chapter 001 ended by asking you to notice shapes.
Keep that habit.
For one house with two features:
x = [rooms, area]
shape: (2,)
For the matching weights:
w = [room_weight, area_weight]
shape: (2,)
The dot product
w · x
returns one number.
Why?
Because every feature contributes one weighted vote, and the votes are added together.
So:
(d,) · (d,) → scalar
If the two vectors do not have the same number of slots, the operation has no sensible pairings.
That shape check will save you from an absurd number of bugs later.
One Warning About Scale
There is a subtle problem hiding in our house vector:
x=[3800].
The number 800 is much larger than 3.
But that does not mean area is automatically “more important” than rooms.
It may simply be measured in different units.
Write the same area in square metres and the coordinate changes again, even though the house does not.
So numerical size and real-world importance are not the same thing.
We will handle feature scaling properly later.
For now remember:
A vector contains coordinates, and coordinates inherit the units we choose.
That choice affects the geometry.
⚠️ Five Ways a Feature Vector Can Lie
A vector is useful only if its coordinates mean what we think they mean.
| Failure | What went wrong |
|---|
| Wrong order | The model thinks slot 1 means rooms, but you put area there. |
| Missing feature | Price depends strongly on location, but location never enters x. |
| Meaningless numeric code | Encoding Delhi =1, Mumbai =2, Chennai =3 accidentally invents distances and order that may have no meaning. |
| Bad scale | One coordinate dominates geometry mainly because of its units. |
| Duplicate information | Area in square feet and area in square metres are the same fact written twice. |
The last one is especially interesting.
If two coordinates are different numbers but contain the same information, how can we tell?
That is exactly where Chapter 006 begins.
A Glimpse of Matrices — Do Not Learn Them Yet
One weight vector asks one weighted question of one input: w⋅x.
A neural-network layer may want many such weighted questions.
So later we will stack many weight vectors together.
That stack is a matrix:
W=w1Tw2T⋮wmT.
Then Wx computes many weighted combinations of the same input.
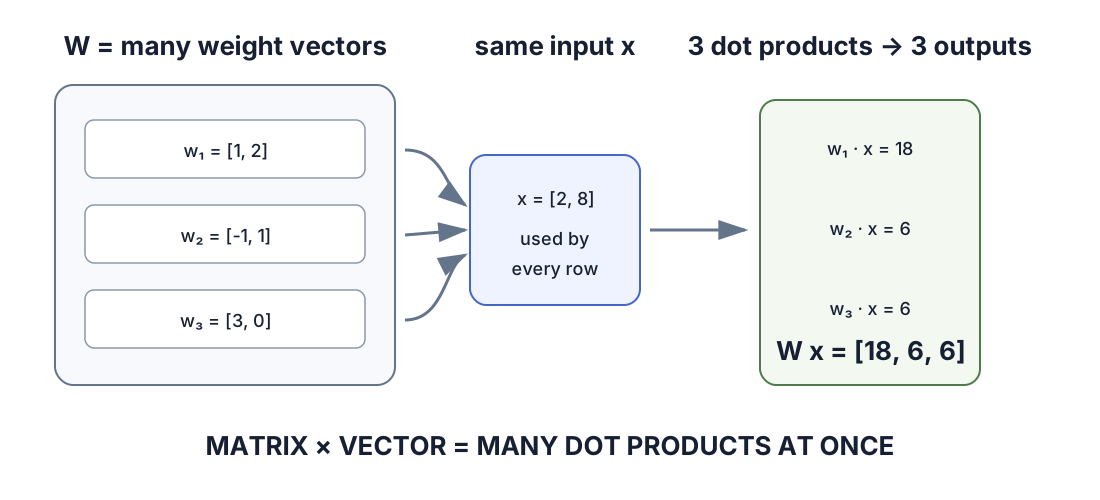
Do not memorize matrix multiplication here.
Chapter 008 will earn matrices properly, and Chapter 009 will show what matrix-vector multiplication does geometrically.
For today keep one preview:
vector = one collection of coordinates
matrix = a structured collection of vectors
That is enough.
🎯 Where This Goes
Yesterday’s model, y^=wx+b, was not thrown away.
It expanded.
Today it is y^=w⋅x+b.
The same pattern will appear again and again:
| Today | Later |
|---|
| house features | model input |
| x | feature vector / representation |
| w | learned weights |
| w⋅x | weighted score |
| many weight vectors | matrix |
| repeated vector transformations | neural-network layers |
| learned vectors | embeddings |
A photograph, a sound segment, a customer, a token, or a hidden state can all be represented by collections of numbers.
The meaning changes.
The mathematics survives.
Distinctions That Matter
| Scalar — one number | Vector — several ordered coordinates |
| Feature — one fact | Feature vector — the facts describing one example |
| World — the actual house | Representation — the numbers the model is allowed to see |
| Coordinate — one slot in a vector | Dimension — how many slots the vector has |
| x — what the example contains | w — how the model weights those contents |
| Element-wise multiplication — keeps separate products | Dot product — pair, multiply, then add to one number |
| Point view — where the example is | Arrow view — direction and amount from the origin |
What We Discovered
- Chapter 001’s learning loop did not fail. Its input representation did.
- A model cannot use information that never appears in its input.
- One measurable or encoded fact is a feature.
- Several features can travel together as one ordered object: a vector.
- The same vector can be read as data, as a point, or as an arrow.
- Vector addition means combining changes; scalar multiplication stretches a vector.
- Each feature can have its own learned weight.
- The repeated operation “pair each feature with its weight, multiply, add” is the dot product.
- Therefore the one-feature model y^=wx+b becomes y^=w⋅x+b.
- That weighted sum is also the arithmetic at the entrance of a neuron.
- Some features can be redundant even when their numbers look different. That unanswered problem leads directly to Chapter 006.
The Mathematics We Built
A d-dimensional feature vector:
x=x1x2⋮xd∈Rd.
A matching weight vector:
w=w1w2⋮wd∈Rd.
Vector addition:
u+v=u1+v1u2+v2⋮ud+vd.
Scalar multiplication:
cu=cu1cu2⋮cud.
Dot product:
w⋅x=i=1∑dwixi=w1x1+w2x2+⋯+wdxd.
The multi-feature linear model:
y^=w⋅x+b
One line replaced a formula that could have contained a million repeated terms.
That compression is what good mathematical notation is for.
What Each Symbol Means
| Symbol | Read it as | Meaning here |
|---|
| xi | “x sub i” | one feature value |
| x | “vector x” | all features for one example |
| d | “dimension” | number of coordinates/features |
| wi | “weight i” | learned importance attached to feature i |
| w | “weight vector” | all feature weights |
| b | “bias” | adjustable offset |
| w⋅x | “w dot x” | pair, multiply, add |
| y^ | “y-hat” | model prediction |
The One-Minute Version
Chapter 001 gave the machine one number per house: the number of rooms.
Then two houses appeared with the same room count but different floor areas.
The machine could not distinguish them because both entered the model as the same input.
So we introduced features.
Instead of one number, a house became
x=[roomsarea].
That ordered collection is a vector.
Each feature gets its own weight, so the old rule y^=wx+b becomes y^=w⋅x+b.
The vector tells the machine what the house contains.
The weight vector tells the model how to combine those facts.
The dot product means pair, multiply, add.
That is the doorway from one-variable machine learning into linear algebra.
🔭 Bridge to Chapter 006 — When Is a New Feature Actually New?
Ramesh likes the new spreadsheet.
Too much.
The next morning he adds more columns:
- rooms,
- area in square feet,
- area in square metres,
- age,
- floor,
- distance to station.
“Six features,” he says proudly.
But area in square feet and area in square metres are not two independent facts.
If you know one, you can calculate the other exactly.
So the vector has six coordinates but perhaps fewer than six genuinely new directions of information.
Now the question changes.
Not:
“How many numbers are in the vector?”
But:
“How many genuinely different directions does this vector space contain?”
To answer that, we need to understand what vectors can build when we add and scale them.
That gives us three ideas:
span, linear independence, and basis.
Next → Chapter 006: How Many Directions Do You Actually Need?