Where We Are
Four houses.
Four prices.
No rule.
Yet the machine has to price a fifth house.
How can it discover a rule that nobody ever gave it?
That’s our starting point.
But there’s a catch.
A house isn’t described by its number of rooms alone. It also has area, location, age, bedrooms, and many other features.
So how do we describe one house using many numbers at once?
Next → Vectors.
1. The Problem: Four Houses and a Question
You work at a small property office. Your manager drops four sales on your desk and asks for a program that prices houses.
| Rooms | Price (₹ lakh) |
|---|
| 1 | 3 |
| 2 | 5 |
| 3 | 7 |
| 4 | 9 |

Then she asks the question that matters:
A five-room house just came on the market. What should we ask for it?
Sit with that for a moment. Nobody has told you a pricing rule. There is no formula in the file. There are four facts and a question about a house that is not among them.
This is the entire problem of machine learning, and it is already here in four rows.
2. What Would a Solution Need?
Before inventing anything, let us reason about what we actually require. A useful solution must:
- Answer for inputs it has never seen. The five-room house is the whole point.
- Come from the data, not from us. If we supply the rule, the machine has learned nothing.
- Be compact. Four rows fit on a desk. Four million do not.
- Be improvable. When it is wrong, there must be a way to make it less wrong.
Keep these four requirements in view. Every idea in this chapter exists because one of them was violated.
3. First Attempt: Write Down the Answers
The simplest possible program stores what we saw:
IF rooms = 1 THEN price = 3
IF rooms = 2 THEN price = 5
IF rooms = 3 THEN price = 7
IF rooms = 4 THEN price = 9
Test it on the four known houses: perfect, every time. A flawless score.
Now ask it about five rooms.
Silence. There is no matching line. The program has no opinion, because it never had an idea — it had a list. Ask it about a three-and-a-half room house and it fails again.
A Tempting Wrong Idea
“It scored 100% on the data, so it is a great model.”
It scored 100% because it memorized the answers. Requirement 1 is violated completely. Perfect performance on examples you have already seen is not evidence of learning — it is the one result you can always achieve by writing things down.
A second tempting fix: take the average of all four prices, ₹6 lakh, and quote that for every house. Now we always have an answer — requirement 1 satisfied! But a one-room flat and a four-room house get the same price. The rule ignores the very thing we were asked about. Remember this ₹6 lakh model; it comes back in §9 to teach us something sharp.
Both attempts fail the same way: neither one captured the relationship between rooms and price.
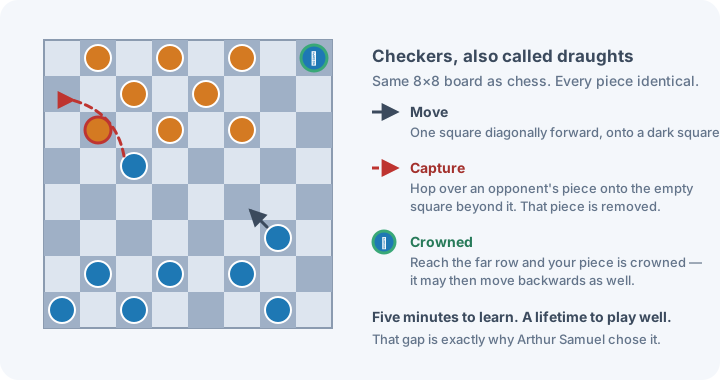
History Lens — Arthur Samuel, IBM, 1950s
🎲 First — what is checkers? You may know it as draughts. Two
players, the same 8×8 chequered board as chess, but far fewer rules: every
piece is identical, moves one square diagonally forward, and captures by
hopping over an opposing piece onto the empty square beyond. Reach the far
row and your piece is crowned — it may then move backwards too. Five minutes
to learn, a lifetime to play well, which is precisely why Samuel chose it.
▶️ How to play Checkers / Draughts (boardgamesTV, 5 min).
Arthur Samuel could not write every rule that makes a good checkers move. Instead, his program adjusted an evaluation of board positions from game outcomes; the work was published in 1959, and the program eventually beat him. The durable idea is simple: when the rule cannot be written down, write a process that improves the rule from experience.
For our houses, the task is pricing, the experience is the four sales, and the performance measure is how close the predictions are. A machine learns when that measure improves through experience. It does not learn merely because it returned the right answer once.
4. The Discovery: A Rule With Adjustable Dials
We stopped looking at the four prices as four separate facts. Let us look at how they change.
rooms:   1  →  2  →  3  →  4
price:   3  →  5  →  7  →  9
change:     +2    +2    +2
Every extra room adds exactly ₹2 lakh. That is not four facts — that is one fact, repeated.
And if each room is worth ₹2 lakh, what is the ₹1 lakh left over at one room? One room costs ₹3 lakh, of which ₹2 lakh is the room itself. Something costs ₹1 lakh before any room exists: the land.
So the relationship is:
price = price-per-room × rooms + base cost of the plot
Now we generalize. We do not yet know that a room is worth ₹2 lakh — we want the machine to find that out. So we leave the two numbers blank and give them names:
y^=wx+b
| Level | The same idea |
|---|
| 💡 Intuition | A machine with two dials. One dial sets how steeply price climbs per room; the other sets the price of an empty plot. Turn the dials until the machine agrees with reality. |
| ✏️ Numbers | With w=2 and b=1: a 3-room house costs 2(3)+1=7. ✓ matches the data. |
| 🎓 Abstraction | y^=wx+b, where w,b∈R are learned from data, not supplied by us. |
Two knobs, and nobody to tell you where to stop
“Two dials” sounds abstract. It is not — you have done this.
Picture an old FM radio, the kind with knobs rather than a screen. One knob
tunes — it decides which station you land on. The other sets the volume —
where the whole thing sits. Nobody hands you the right positions; there is no
manual saying “turn to 4.2.” You turn a little, you listen, and the static tells
you whether you are closer.
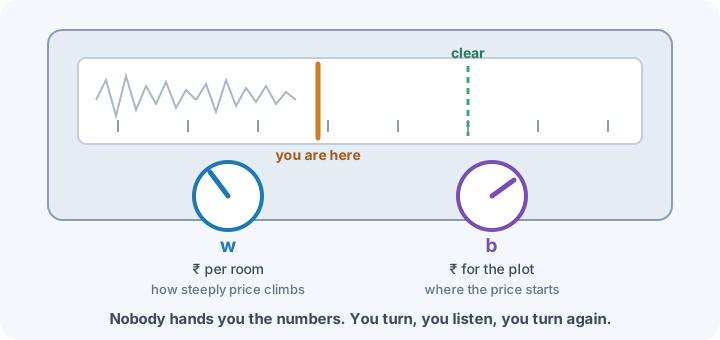
Our machine has exactly two knobs, and the same three things are true of them:
- Getting one right is not enough. Perfect tuning at zero volume is
silence. In the same way w=2 with b=0 still prices every house ₹1
lakh short — the slope is right and the answer is still wrong.
- The static is the score. That hiss is one number standing for how wrong
you are. §10 gives it a name: the loss.
- You do not know which way to turn until you move. Nudge the dial; if the
hiss drops, keep going that way. That is not an analogy for gradient descent.
It is gradient descent, and §15 writes it as arithmetic.
And how far you turn matters as much as which way. Nudge the dial in
millimetres and you will be there all evening. Spin it hard and you fly past
the station, then past it again on the way back. That is η, the learning
rate — and §18 shows a machine doing exactly that, swinging wider each time
until the numbers overflow.
Every symbol, in English:
| Symbol | Read it as | Meaning here | In code |
|---|
| x | “the input” | number of rooms | x |
| y | “the true answer” | the price the house actually sold for | y |
| y^ | “y-hat”, our guess of y | the price our rule predicts | y_hat |
| w | “weight” | ₹ lakh added per room | w |
| b | “bias” | ₹ lakh before any rooms — the plot | b |
The hat matters. y is what the world did. y^ is what we claim. Learning is the business of closing the gap between them.

Notice what we bought: two numbers now stand in for the whole table, and unlike the lookup table, y^=wx+b has an answer for five rooms, for 3.5 rooms, for any x at all. Requirements 1 and 3, satisfied.
5. Prediction Is Not Learning
We have the form of the rule. We do not have the two numbers. The machine must find them, so it cannot start from the answer. Let it start ignorant:
w=1,b=0⟹y^=x
Ask it about a three-room house:
y^=1(3)+0=3but the house sold fory=7.
The machine answered. The machine was wrong by ₹4 lakh. And notice — it will be wrong in exactly the same way tomorrow, and the day after. It has no mechanism to improve.
Think — This is the distinction the whole chapter turns on:
Prediction is what a model does: run the input through the current dials.
Learning is what changes the dials themselves, using evidence.
A calculator predicts. It never learns.
To change the dials we need to know how wrong we are — not as a feeling, but as a number. Requirement 4 has arrived, and we cannot satisfy it yet.
6. Which Numbers Belong to the World, and Which to the Model
Stop and look at what is now on the page. The three-room house, priced by the ignorant dials w=1, b=0:
3, 1, 0, 3, 7, −4, 16
Seven numbers. On paper they are identical in kind — digits in a row. They could not be doing more different jobs.
- The first
3 is a fact about a house. Nobody chose it.
1 and 0 are the dials. The machine chose them, badly, and may choose again.- The second
3 is the machine’s answer.
7 is what the world actually did.−4 is the gap between those two.16 is what we have decided that gap should cost.
Mix these together and learning looks like arithmetic with no direction. Keep them apart and every later idea — gradients, backpropagation, attention — stays legible. So here is the whole vocabulary, earned rather than announced:
| Role | Symbol | Where it comes from | Can training change it? |
|---|
| Input | x | the world — what the model is allowed to see | ❌ |
| Target | y | the world — what actually happened | ❌ |
| Parameters | w,b | the model — its adjustable memory | ✅ |
| Prediction | y^ | computed from x and the parameters | — |
| Error | e=y^−y | comparing the two above | — |
| Loss | L | our chosen price for that error | — |
A Tempting Wrong Idea — ”x is in the formula too. Why is it not a parameter?”
Because the house has three rooms whether the model likes it or not. The machine may turn w and b to reduce its loss. It may not decide the house has four rooms because that would be cheaper to be right about.
The input is not “everything you know.” Suppose you already knew what the three-room house eventually sold for, and you handed that in as an input. The model would score perfectly and would have learned nothing — because at the moment a real prediction is needed, for a house that came on the market this morning, that number does not exist yet.
The input may contain only information that would genuinely be available at the moment the prediction has to be made.
Break that rule and you have data leakage: a model that looks superb in testing and is worthless in the office. Level 05 treats it as the serious failure it is.
And one set of dials has to serve every house. It is tempting to give house i its own private (wi,bi). Every training house would then be priced exactly right. But ask what happens when the fifth house arrives and there is no (w5,b5) to reach for — and you will recognise §3’s lookup table, wearing algebra as a disguise.
The pressure that makes learning work is precisely this: the same two numbers are forced to explain all four houses. A rule that must fit every example cannot simply memorise them one at a time. That pressure is where generalization comes from, and Level 05 exists to measure whether it held.
7. What Would a Measure of Wrongness Need?
Again, reason before inventing. A useful measure must:
- Be one number for the whole dataset — not four complaints, one verdict.
- Be zero when every prediction is perfect.
- Grow as predictions get worse.
- Never let a miss in one direction cancel a miss in the other.
That fourth requirement looks fussy. §9 is about to show you why it is the one that matters.
8. First Attempt at a Measure: Count How Many We Got Right
Before averaging anything, try the measure a human reaches for first: how many did we get right?
The ignorant model — w=1, b=0 — predicts 1,2,3,4 against truths of 3,5,7,9. Correct: none. Score 0%.
Now hand the machine a genuinely good set of dials. Close, but not exact:
| Rooms | Prediction | Truth | Right? |
|---|
| 1 | 2.9 | 3 | ✗ |
| 2 | 4.9 | 5 | ✗ |
| 3 | 6.9 | 7 | ✗ |
| 4 | 8.9 | 9 | ✗ |
Every quote is within ₹10,000 of the true price. Any estate agent alive would take it and go home. Score: still 0%.
The measure cannot distinguish a hopeless model from a nearly perfect one. It fails requirement 3 — it does not grow as predictions get worse, it sits flat and then jumps. And a measure that reads the same before and after a real improvement cannot possibly tell us which way to turn a dial.
The lesson outlives the example. The number you report and the number you train on need not be the same number, and often cannot be. “How many did we get right” is how you would describe the model to Meera. It is useless for improving it. §11 gives this its proper name.
9. Second Attempt at a Measure: Just Average the Errors
The obvious move. For each house, compute y^−y, then average.
Return to that ₹6 lakh model from §3 — the one that quotes the same price for every house:
| Rooms x | Prediction y^ | Truth y | Error y^−y |
|---|
| 1 | 6 | 3 | +3 |
| 2 | 6 | 5 | +1 |
| 3 | 6 | 7 | −1 |
| 4 | 6 | 9 | −3 |
Average error:
4(+3)+(+1)+(−1)+(−3)=40=0.
Zero. By this measure, a model that completely ignores the number of rooms is flawless.
A Tempting Wrong Idea
Averaging signed errors lets overcharging on small flats pay for undercharging on large houses. The books balance; every individual customer is still quoted the wrong price. Requirement 4, violated exactly as promised.
The problem is the minus signs. We need the size of each mistake, with its direction thrown away.
10. The Discovery: Squared Error and the Loss Function
Two honest ways to discard a sign. Take the absolute value, or square it.
| Rooms | Error | ∣error∣ | error2 |
|---|
| 1 | +3 | 3 | 9 |
| 2 | +1 | 1 | 1 |
| 3 | −1 | 1 | 1 |
| 4 | −3 | 3 | 9 |
| avg | 2 | 5 |
Both refuse to report zero. Both do the job. So why does this course — and most of deep learning — reach for the square?
- Big misses hurt more than small ones. Doubling an error quadruples its cost: being ₹3 lakh wrong contributes 9, while being ₹1 lakh wrong contributes 1. Squaring says one catastrophic quote is worse than three small ones, which is usually what we believe about pricing houses.
- It is smooth. ∣e∣ has a sharp corner at zero where its slope is undefined. From §15 onward, slopes are the only tool we have for improving the dials — so a kink is a genuine obstacle. e2 is smooth everywhere.
Squaring is a choice, not a law. It is unusually sensitive to outliers: one wildly mispriced mansion can dominate the whole average. Mean absolute error is a perfectly respectable alternative, used precisely when outliers should not dominate. We square because of the two reasons above, not because the universe demands it.
Write it for one house — the squared error:
L=(y^−y)2
and for the whole dataset, the mean squared error:
MSE=n1i=1∑n(y^i−yi)2
If ∑ is new, read it left to right as an instruction:
i=1∑n(y^i−yi)2⟶"start at house i=1, square its error, add it on, move to the next, stop at n."
The subscript i is just a house number; n is how many houses there are. With n=4 it unpacks to
(y^1−y1)2+(y^2−y2)2+(y^3−y3)2+(y^4−y4)2, divided by 4. Nothing more.
This number has a name: the loss. And something quietly enormous just happened —
We turned the vague wish “the machine should get better” into a quantity we can compute. Anything we can compute, we can try to make small.
Check the measure against our models:
| Model | What it does | MSE |
|---|
| w=0,b=6 | ignores rooms | 5 |
| w=2,b=0 | right slope, forgot the land | 1 |
| w=2,b=1 | the truth | 0 |
The ranking matches our judgement. The measure works.
What squaring actually buys, in numbers. Two models, four houses apiece:
| Errors | MAE | MSE |
|---|
| Model A | 2,2,2,2 | 2 | 4 |
| Model B | 0,0,0,8 | 2 | 16 |
Absolute error cannot tell them apart — both are off by 8 in total. Squared error calls Model B four times worse. Which is right? Neither, universally. Model A quotes every customer slightly wrong; Model B quotes three customers perfectly and one catastrophically. Squaring is the decision that one disaster is worse than four inconveniences. For house prices — where the badly quoted customer walks out and tells the whole neighbourhood — that is usually the decision you want.
The same lever, pulled the other way:
| Errors | MAE | MSE |
|---|
| 1,1,1,1,20 | 4.8 | 80.8 |
One bad number out of five drags the MSE from roughly 1 to over 80. If that 20 is a genuine mansion, good — you want the model to care. If it is a slipped digit in the register, squaring has just handed your entire training run to a typo.
History Lens — Legendre, Gauss, and the quarrel over least squares
Around 1800, astronomers had a version of Meera’s problem. Repeated observations of the same object disagreed with one another, because instruments are imperfect and so are the people reading them. Which orbit was the orbit?
Adrien-Marie Legendre published the answer in 1805: choose the curve that makes the sum of squared residuals smallest. He called it la méthode des moindres carrés — the method of least squares. Four years later Carl Friedrich Gauss published the same method and remarked that he had been using it since 1795, which Legendre never forgave. Gauss then went further than the quarrel and asked why squares — showing that if measurement noise has a particular bell-shaped distribution, least squares is not a convenient choice but the provably correct one.
With four houses and a page of arithmetic, we are doing what they did for the orbit of Ceres. The question — when honest observations disagree, what should “best fit” mean numerically? — is the same one, and it is two centuries older than the computer. Level 03 finishes Gauss’s argument properly.
11. A Loss Is a Statement of Priorities
We have quietly done something that deserves naming. We did not discover that a mistake costs the square of its size. We decided it.
L(y^,y)=what it costs to say y^ when the truth was y
That is all a loss function ever is: a rule for valuing mistakes. Change the rule and you change what the machine will work hardest to avoid.
Squaring treats ₹4 lakh too high and ₹4 lakh too low as the same sin. Look at that honestly for a moment. To the buyer they are not the same, and to the seller they are not either. Nothing prevents us writing a loss that charges more for overpricing than for underpricing. It is our rule; we may write what we like.
That freedom reaches far past houses:
- A screening model that misses a dangerous condition has done something far worse than one that orders an unnecessary second test. The loss should say so, in numbers.
- A warehouse that understocks loses customers; one that overstocks loses money to waste. Rarely in equal measure.
A loss function is where a human value judgement enters a system that has none of its own. The machine will minimise whatever you write down, exactly and without argument. This is the point in the whole pipeline where you are responsible for what it learns to care about — and the reason “the model optimised precisely what we asked it to” opens so many post-mortems.
Loss and metric are two different jobs. §8 watched accuracy fail as a training signal; it remains an excellent way to describe a model to a human being. Most real systems carry both, and they are rarely the same function:
| Task | Trained on | Reported as |
|---|
| house prices | mean squared error | mean absolute error, in ₹ |
| image classification | cross-entropy | accuracy, F1 |
| language models | cross-entropy | perplexity, benchmark scores |
The loss has to be smooth enough to optimise. The metric has to be meaningful enough to argue about in a room full of people. Asking one number to do both jobs is the reliable way to end up with neither.
12. Learning Becomes a Search
Now the problem has a shape. Every pair (w,b) defines a line; every line produces predictions; every set of predictions produces one loss. So:
learning=find the (w,b) that makes L smallest.
With two dials you could hunt by hand. Try w=1, try w=2, keep what is better.
But count what happens when the model grows. A small image model has millions of dials; a large language model has hundreds of billions. Testing ten values of each is 10billions combinations. There is not enough time in the universe.
Next Question — Guessing does not scale. Is there a way to know which direction to turn a dial without trying every value?
13. The Discovery: The Loss Landscape
Let us look at what the loss actually does as a dial turns. Hold b=1 and walk w through some values, computing MSE on our four houses by hand:
| w | Predictions | Loss L |
|---|
| 0 | 1, 1, 1, 1 | 30.0 |
| 1 | 2, 3, 4, 5 | 7.5 |
| 1.5 | 2.5, 4, 5.5, 7 | 1.875 |
| 2 | 3, 5, 7, 9 | 0 |
| 2.5 | 3.5, 6, 8.5, 11 | 1.875 |
| 3 | 4, 7, 10, 13 | 7.5 |
| 4 | 5, 9, 13, 17 | 30.0 |
Look at the shape: falling, bottoming out at w=2, rising again — and symmetric around the bottom. That symmetry is a clue. Let us find the exact formula.
With b=1 and true prices yi=2xi+1, the error on house i is
y^i−yi=(wxi+1)−(2xi+1)=(w−2)xi.
The +1 cancels — a fixed offset that both lines share. Now square and average:
L(w)=n1i=1∑n[(w−2)xi]2=(w−2)2⋅n1i=1∑nxi2.
(w−2)2 came out of the sum because it does not depend on which house we are looking at. The leftover piece is a property of our data alone:
n1∑xi2=412+22+32+42=430=7.5.
L(w)=7.5(w−2)2
Check it against the table: L(0)=7.5(4)=30 ✓, L(1)=7.5(1)=7.5 ✓, L(2)=0 ✓. The hand calculations and the algebra agree exactly.
This is a parabola — a valley with exactly one bottom, at the correct answer w=2.
14. The Corner That Squaring Avoids
§10 claimed that ∣e∣ has a sharp corner at zero where its slope is undefined, and asked you to take it on trust. We are about to need slopes for everything, so let us pay that debt with arithmetic.
Fix one house — the three-room one, y=7 — and walk the prediction y^ past the truth, drawing both costs:
   absolute error  |ŷ − 7|              squared error  (ŷ − 7)²

 6|\           /                    36|\               /
 5| \         /                     25| \             /
 4|  \       /                      16|  \           /
 3|   \     /                        9|   \         /
 2|    \   /                         4|    \       /
 1|     \ /                          1|     \__ __/
 0|------●------→ ŷ                  0|--------●------→ ŷ
        7                                     7

        a V                                  a U
The V has a corner. The U has a rounded bottom. Now make that difference numerical, because “corner” is a word and we want a number.
Stand just to the left of the truth, at y^=6.90, where L=0.10. Step right by 0.01 and the loss falls to 0.09. Downhill is to the right, and the ground drops by exactly 1 unit of loss per unit of step.
Stand just to the right, at y^=7.10, where L=0.10 again. Step right by 0.01 and the loss rises to 0.11. Downhill is now to the left, and the ground climbs by exactly 1 per unit of step.
| Where you stand | Slope of ∣e∣ |
|---|
| anywhere left of 7 | −1 |
| anywhere right of 7 | +1 |
| at exactly 7 | both — which means neither |
Approach the point from the left and the slope is −1; approach from the right and it is +1. One point cannot hold two slopes, so at the corner there is no slope at all. And notice what never changes on either side: the slope reads −1 whether you are ₹0.1 lakh too low or ₹100 lakh too low. Absolute error tells you which way to walk and never how far.
Now run the identical experiment on (y^−7)2:
| y^ | Error e | Loss e2 | Measured slope |
|---|
| 5 | −2 | 4 | ≈−4 |
| 6 | −1 | 1 | ≈−2 |
| 6.9 | −0.1 | 0.01 | ≈−0.2 |
| 7 | 0 | 0 | 0 |
| 7.1 | +0.1 | 0.01 | ≈+0.2 |
| 8 | +1 | 1 | ≈+2 |
| 9 | +2 | 4 | ≈+4 |
Read the last column against the second. The slope is 2e, every single time:
dy^dL=2(y^−y)
We just found a derivative by reading a table — which is worth noticing. Nothing here required calculus, only the willingness to compute a quantity twice and subtract.
The shape of that column is the real prize:
far from the truth   →  large slope   →  take a big correction
near the truth       →  small slope   →  tread carefully
at the truth         →  slope zero    →  stop
Absolute error reports ±1 everywhere and then refuses to answer at the bottom. Squaring hands us a signal carrying both direction and urgency, readable all the way down to zero. That is the whole reason §10 chose it, and §15 is about to spend it.
Smooth does not mean flat. At an error of 100 the slope of e2 is 200 — brutally steep, and perfectly smooth. Smooth means the direction never jumps. It says nothing at all about how steep the ground is.
🔗 One thing the table quietly hides. We nudged the prediction and watched the loss. But the machine cannot reach in and set y^ directly — it owns only w and b. The influence travels down a chain:
w → ŷ = wx + b → e = ŷ − y → L = e²
Turn w and the prediction moves; move the prediction and the error moves; move the error and the loss moves. §15 works out the slope at the far end of that chain for our four houses. Doing the same for a chain a hundred links long is the chain rule, and the algorithm that walks it backwards is backpropagation — Level 02, and the reason that level exists.
15. Which Way Is Downhill?
Stand at w=0, blindfolded, somewhere on that valley wall. You cannot see the bottom. But you can feel the ground under your feet: is it tilting up or down, and how steeply?
Measure the tilt the obvious way — take a tiny step h and see how much the loss changed, per unit of step:
tilt≈hL(w+h)−L(w)
Let us actually compute it for L(w)=7.5(w−2)2. Expand the top:
L(w+h)−L(w)=7.5[(w+h−2)2−(w−2)2]
Write (w−2+h)2=(w−2)2+2(w−2)h+h2 and the (w−2)2 terms cancel:
=7.5[2(w−2)h+h2]
Divide by h:
hL(w+h)−L(w)=7.5[2(w−2)+h]=15(w−2)+7.5h
Now the key move. Our step h was arbitrary — so make it smaller and smaller. The term 7.5h shrinks away to nothing, and what survives is the tilt at the point itself:
slope at w=15(w−2)
No calculus was assumed. We expanded a square, divided, and watched what refused to disappear. (The notation for “shrink h to nothing” is h→0, and the machinery around it is the derivative — Chapter 018 builds it properly, and Chapter 023 turns it into an algorithm.)
In mathematics h shrinks to nothing. In code it cannot. A computer stores numbers to finite precision, so subtracting two nearly equal losses eventually leaves you with rounding noise instead of a slope. Gradient checks in practice use h around 10−5 — small enough to be accurate, large enough to survive the arithmetic. The gap between exact mathematics and floating-point computation opens right here, and it never quite closes.
Read the answer:
| Position | Slope 15(w−2) | Meaning | Move |
|---|
| w=0 | −30 | ground falls away to the right | increase w |
| w=1 | −15 | still downhill to the right, less steeply | increase w |
| w=2 | 0 | flat — the bottom | stop |
| w=3 | +15 | ground rises to the right | decrease w |
Intuition — The slope is a compass. Its sign says which way is downhill; its size says how steep the ground is. Move against the slope and the loss falls.
“Move against the slope” is a rule we can write down. It is the rule the entire field runs on:
θ←θ−η∇θL
Every symbol, in English:
| Symbol | Read it as | Meaning |
|---|
| θ | “theta” | all the dials at once — here, θ=(w,b) |
| ← | “is replaced by” | this is an update, not an equation to solve |
| ∇θL | “grad L” | the collection of slopes, one per dial |
| η | “eta” | the learning rate — what fraction of a step we take |
| − | the crucial minus | downhill is against the slope |
For our two dials the slopes are (Chapter 021 derives these; here, take the form and check it numerically):
∂w∂L=n1∑2(y^i−yi)xi,∂b∂L=n1∑2(y^i−yi)
Read ∂w∂L as: “if I nudge w by a tiny amount and leave b alone, how much does the loss move?”
16. The Geometry: A Valley With a Single Bottom
With one dial, the loss is a curve — the parabola of §13.

With two dials, L(w,b) is a surface — a bowl in three dimensions, with (w,b)=(2,1) at the lowest point. Training is a ball released on the inside of that bowl.
This picture is worth holding onto, because almost everything later is a complication of it: deep networks have landscapes in millions of dimensions, full of ridges, plateaus and saddle points. But the move is always the same — feel the slope, step downhill, repeat.
Our bowl has exactly one bottom because y^=wx+b is linear and the loss is squared; this combination is convex. Deep networks are not convex, and that is a genuine difference, not a detail. Later chapters on neural-network optimization take that difference seriously.
17. The Learning Loop
Everything so far assembles into one cycle:

Hand Calculation — one full step of learning
Start ignorant: w=0, b=0, and choose η=0.01.
Predict. y^=0⋅x+0=0 for every house: [0,0,0,0].
Measure. Errors y^−y=[−3,−5,−7,−9], so
L=49+25+49+81=4164=41.
Slopes.
∂w∂L=42[(−3)(1)+(−5)(2)+(−7)(3)+(−9)(4)]=42(−70)=−35
∂b∂L=42[(−3)+(−5)+(−7)+(−9)]=42(−24)=−12
Both slopes are negative: both dials are too small. The compass says turn them up.
Update.
w←0−0.01(−35)=0.35
b←0−0.01(−12)=0.12
Check. New predictions [0.47,0.82,1.17,1.52] give L=28.45.
The loss fell from 41 to 28.45 in a single step, and nobody told the machine that a room is worth ₹2 lakh.
Repeat that step 2000 times and the dials arrive at w=2.0002, b=0.9993 — the machine has discovered ₹2 lakh per room and ₹1 lakh for the land. Asked about the five-room house it finally answers:
y^=2.0002(5)+0.9993≈11 lakh
There is no function called learn() anywhere in this. Learning is arithmetic, repeated:
predict → measure → find the slope → step downhill → repeat
18. 🔬 The Experiment: How Big Should a Step Be?
η is ours to choose — the machine cannot learn it from the data. So what happens if we choose badly?
Predict before you read on. Three runs, 200 steps each, identical in every way except η: one at 0.001, one at 0.01, one at 0.13. Which reaches w=2,b=1? What does failure look like — a wrong answer, or something else?
Here is what the arithmetic does (you can reproduce every row with a short Python loop):
| η | After 200 steps | Loss | Verdict |
|---|
| 0.001 | w=2.020,b=0.706 | 0.061 | crawling — b is still far from 1 |
| 0.01 | w=2.054,b=0.843 | 0.004 | working |
| 0.05 | w=2.005,b=0.986 | 0.00003 | working well |
| 0.13 | w→±∞ | overflow | exploded |
The failure is the interesting one. Watch the first four steps at η=0.13:
step 0:  w = 0.00   loss = 41
step 1:  w = 4.55   loss = 56     ← overshot past 2, landed further out
step 2:  w = -0.79  loss = 77     ← overshot back, worse again
step 3:  w = 5.46   loss = 106    ← each swing is bigger
It is not drifting to a wrong answer. It is oscillating across the valley, overshooting a little further every time, until the numbers overflow. The step is so long that it jumps from one wall of the valley to a higher point on the opposite wall.
And this threshold is not mysterious — it is predictable from the curvature we computed in §13. The mathematics says instability begins near η≈0.12, and the experiment breaks between 0.11 (converges) and 0.12 (diverges). Theory and machine agree.
Too small and you never arrive. Too large and you are thrown out of the valley. η is a hyperparameter — chosen by us, not learned from data.
19. How It Breaks
Learning is not automatic. Five ways this exact setup fails:
| Failure | What it looks like | Why |
|---|
| Wrong model class | loss stops falling while still large | A straight line cannot fit a curved relationship. No (w,b) exists that works. |
| Wrong loss | loss small, users unhappy | You optimized what you measured, and you measured the wrong thing. |
| Bad learning rate | crawling, or overflow | §18. |
| Uninformative input | no better than guessing | If rooms genuinely do not affect price, no method recovers a signal that is not there. |
| Memorization | perfect on training data, poor on new houses | The §3 lookup table in a more sophisticated costume. This is overfitting; the generalization chapters build train/validation/test splits to detect it. |
Common Mistake — treating a falling loss as proof of success. A falling training loss only proves you are fitting the data you already have. The question is always the five-room house you have not seen.
20. Shapes: A Habit Worth Starting Now
Our four houses are not four separate numbers — they are one array:
x=[1,2,3,4]∈R4,y=[3,5,7,9]∈R4
R4 reads as “four real numbers in a row.” When we write y^=wx+b, one line multiplies all four houses at once:
   x: (4,)        w: scalar
       ↓ multiply every entry, add b to every entry
   ŷ: (4,)
Shape in, shape out. It looks trivial with four numbers and one dial. In the later transformer chapters you will be tracking (batch, tokens, heads, dim) through an attention block, and the reader who started checking shapes in Chapter 1 will be the one who survives it.
21. 🎯 Machine Learning Connection
What we built in this chapter is not a warm-up for deep learning. It is deep learning, at the smallest size that still works.
| This chapter | A modern neural network |
|---|
| y^=wx+b | y^=fθ(x) — many such transformations composed |
| 2 parameters | 106 to 1012 parameters |
| MSE | cross-entropy, contrastive, preference losses… |
| slope by hand | backpropagation (Chapter 027) |
| gradient descent | Adam, AdamW (Chapter 095) |
| 4 houses | terabytes of text |
The loop does not change. A language model predicting the next word is running §17: predict, measure the loss, compute slopes, step downhill, repeat — a few hundred billion dials instead of two.
A model has parameters. Data produces a loss. Slopes say how to change the parameters. Everything else in this course is a refinement of that sentence.
22. Distinctions That Matter
| Prediction — running the current model | Learning — changing the model using evidence |
| Error — signed, y^−y, has direction | Loss — a chosen function of error, built to be minimized |
| Parameter — w,b, learned from data | Hyperparameter — η, chosen by you |
| Memorizing — perfect on seen data | Generalizing — correct on unseen data |
| y — what the world did | y^ — what the model claims |
| Input — observed, fixed by the world | Parameter — adjustable, owned by the model |
| Loss — chosen to be optimized | Metric — chosen to be reported to a human |
| Per-example loss — judges one quote | Dataset objective — one verdict over all four |
23. What We Discovered
- Writing rules by hand fails whenever the rule is unknown or too complicated to state — so we write the process that finds the rule instead.
- A model is a formula with adjustable dials. The dials carry meaning: ₹ per room, ₹ per plot.
- Predicting and learning are different acts. Only one of them changes the dials.
- “How wrong are we?” must become a single computable number, and signed errors cancel — so we square them.
- Once wrongness is a number, learning becomes a search for its minimum.
- The loss forms a landscape. Its slope is a compass: sign gives direction, size gives steepness.
- Step against the slope, repeatedly, and the dials find values nobody supplied.
- Step size is ours to choose, and choosing badly breaks the whole thing.
- The numbers in the loop are not interchangeable: inputs and targets come from the world and cannot be edited, parameters belong to the model and are the only things training may touch.
- One set of dials must explain every example. That pressure — not the arithmetic — is what separates learning from memorizing.
- A loss is a value judgement written as a formula. Squaring says a single disaster is worse than several inconveniences; another loss would say something else, and the machine would dutifully believe it.
24. Mathematics We Built
y^=wx+b
MSE=n1i=1∑n(y^i−yi)2
L(w)=7.5(w−2)2(this dataset, b=1)
slope=h→0limhL(w+h)−L(w)=15(w−2)
∂w∂L=n1∑2(y^i−yi)xi∂b∂L=n1∑2(y^i−yi)
θ←θ−η∇θL
25. What Each Symbol Means
| Symbol | English | In code |
|---|
| x | input (rooms) | x |
| y | true answer (actual price) | y |
| y^ | prediction | y_hat |
| w | weight — ₹ lakh per room | w |
| b | bias — ₹ lakh for the plot | b |
| n | number of examples | n |
| e | error — signed gap, y^−y | error |
| L | loss — one number for total wrongness | loss |
| ∑i=1n | “add up over all examples” | .sum() |
| θ | all parameters together | (w, b) |
| ∇θL | the slopes, one per parameter | dw, db |
| η | learning rate — step size | learning_rate |
| ∂L/∂w | “nudge w only; how much does L move?” | dw |
26. One-Minute Explanation
Explain to someone with no mathematics, using no equations:
Why can a machine price a house it has never seen, when all it was given was four old sales?
If you need the word “gradient” to get through it, you have not finished understanding it.
27. Exercises
Level 1 — Observe. Look at the §13 loss table. Why are L(1) and L(3) both exactly 7.5? What does that symmetry say about the shape of the landscape — and would it still hold if the four houses had prices 3,5,7,20?
Level 2 — Calculate (by hand, no code). A model has w=3, b=0. For the four houses: write the four predictions, the four errors, and the MSE. Is this model better or worse than w=0,b=6? Then do one gradient-descent step with η=0.01 and confirm the loss went down.
Level 3 — Derive. We showed L(w)=7.5(w−2)2 with b pinned to 1. Now redo it with b pinned to 0: prove that
L(w)=7.5w2−35w+41, and find the w that minimizes it by setting the slope to zero. You should get w=7/3, with a minimum loss of 1/6. Why is the answer not exactly 2? What is the model doing to compensate for a plot price it is forbidden to use?
Level 4 — Investigate (notebook Steps 8–11). Find the largest η that still converges, to two decimal places. Then change the data to x=[10,20,30,40] with the same prices and find the threshold again. It moves sharply — explain why, using n1∑xi2 from §13.
Level 5 — Design. Your loss is now used to price houses for real families. Squared error treats a ₹4 lakh overcharge and a ₹4 lakh undercharge as identical mistakes — but they are not, to the buyer or the seller. Design a loss function that punishes overcharging more heavily. Write it mathematically. What properties must it keep to remain usable (think about §10 and §15)? What does your choice do to the machine’s behaviour?
28. Common Mistakes
| Mistake | Why it is wrong |
|---|
| “Training loss went down, so the model is good.” | It proves fitting, not generalizing. Ask about the unseen house. |
| “The model understands houses.” | It found two numbers that fit four rows. There is no concept of house in it. |
| “More parameters means better learning.” | More dials can fit more shapes — and memorize more noise. The generalization chapters make this tradeoff explicit. |
| “The error is zero on average, so we are accurate.” | §9. Cancellation hides every individual mistake. |
| ”η can just be set very small to be safe.” | Then you never arrive. Slowness is a failure too. |
| “Deep learning is something different from this.” | It is this loop, with a bigger model and better slopes. |
| ”x is in the formula, so it is a parameter too.” | Training may change the model, not the house. Only w and b are learnable. |
| “Making a prediction means the model learned.” | Prediction reads the dials; learning moves them. A calculator predicts forever and learns nothing. |
| “A negative error means the model is bad.” | The sign says only which side of the truth you landed on. §14 turns that sign into a direction to walk. |
| “Give each house its own w and b — it fits perfectly.” | And has nothing at all to say about the fifth house. That is §3’s lookup table again. |
| “Just train on the number we report.” | Accuracy is flat between improvements (§8). A training signal must respond to small changes. |
| “Squared error is simply the correct loss.” | It is a choice about what mistakes should cost, and an outlier-sensitive one (§10). |
29. Socratic Questions
Answers are deliberately not given. Sit with them.
- Why do we divide by n in the MSE? What breaks if we merely sum?
- Why does squaring feel more “natural” than cubing the error? What would ∣e∣3 do?
- The slope at the bottom of the valley is zero. Is every point with zero slope a bottom?
- We chose η ourselves. Could a machine learn η too? What would that even mean?
- Our four houses lay exactly on a line. Real data never does. What is the machine minimizing then — and is “the true rule” still something it can find?
- If the lookup table in §3 had contained a million houses, would it still be wrong to call it learning?
- Two different (w,b) pairs can give the same prediction for one house. So how many houses does it take before the data pins the dials down?
- Absolute error reports a slope of ±1 no matter how wrong you are. Is there a situation where not knowing how far off you are is an advantage?
- If a loss encodes what we want, and the model minimizes it exactly, whose fault is a model that behaves badly?
- You are told a model reached zero training loss. What is the first question you should ask?
30. 🔭 Bridge to Chapter 005 — When One Number Per House Is Not Enough
We built a learner, and it is complete. It has a form, y^=wx+b. It has a conscience, the mean squared error. It has a way to improve — feel the slope, step against it, repeat. Every one of those parts survives intact into models with a hundred billion dials. Nothing in the rest of this course replaces them; it only makes each one bigger.
What does not survive is the word one.
One number per house. Tomorrow Meera drops two more files on your desk, both three-room houses, sold for very different money — because one is 800 square feet facing a main road and the other is 1,600 facing a park. Rooms alone cannot tell them apart, and no amount of turning w will fix that. The input has stopped being a number. It is a list.
The moment a house needs three measurements instead of one, y^=wx+b runs out. You need a way to hold many numbers as a single object, to multiply a whole collection of dials against a whole collection of measurements in one stroke, and then to do that for four thousand houses at once without writing four thousand lines.
That object is the vector, and Chapter 005 begins there.
🧭 Where the road goes from here. Level 01 gives you the notation for many numbers at once. Level 02 gives you every slope at once, which is the only reason models with billions of dials can be trained at all. Level 03 answers the question this chapter left open: where do loss functions actually come from, and was the loss genuinely lower or did four houses simply flatter us?
Each of those levels opens because something in this chapter stopped working. You have already met all three walls.
Everything else in this chapter, you now carry with you.
What You Will Need, and When
This chapter used four houses, two dials, and arithmetic you could do on paper.
Nothing more was required, and that was deliberate.
It does not stay that way. Three branches of mathematics are waiting, and each
one arrives because something in this chapter stops working.
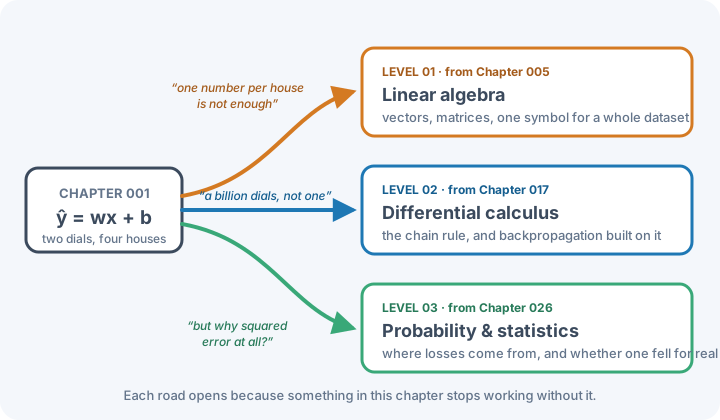
Linear algebra — when one number per house is not enough
Tomorrow you are handed two houses with the same number of rooms and different
prices, because one is 800 square feet and the other is 1,600.
Now a house needs two numbers. Then five. A photograph needs a million.
You cannot write w1x1+w2x2+⋯+w1000000x1000000 and do
anything useful with it. You need notation in which “multiply every input by
its weight and add them up” is a single symbol — and “now do that for four
thousand houses at once” is one more.
That notation is vectors and matrices.
→ Level 01, from Chapter 005.
🎥 See it before you study it — Essence of Linear
Algebra,
3Blue1Brown. Fifteen short videos, and the one that matters most for us is
“Linear transformations and matrices”: a matrix is not a grid of numbers to be
memorised, it is a thing that moves space. Watch that, and the notation in
Level 01 stops looking like bookkeeping.
Differential calculus — when you cannot feel the slope by hand
We found the slope of L(w)=7.5(w−2)2 by taking a tiny step h and watching
what happened. That works when there is one dial.
A modern model has billions. You cannot nudge each one and re-measure — that is
the combinatorial explosion from §12 wearing a different hat.
You need a way to get every slope at once, symbolically, and a rule for how a
change buried deep inside a long chain of operations affects the number at the
end. That rule is the chain rule; the machinery built on it is
backpropagation.
→ Level 02, from Chapter 017.
🎥 See it before you study it — Essence of
Calculus,
3Blue1Brown. Start at “The paradox of the derivative”. What we did by hand in
§15 — nudge w by a tiny h, see what the loss did — is exactly the picture
that series draws, and the chain rule arrives in it as a shape rather than a
formula to recite.
Statistics and probability — when you ask why squared error
We chose to square the error, and §10 admitted plainly that this was a choice
rather than a law. That should have bothered you. Where do loss functions
actually come from?
The answer is maximum likelihood: assume the noise in house prices has a
particular shape, and squared error falls out as the thing you should
minimise. Not a convention — a consequence.
Statistics also answers the question this chapter kept deferring: the loss fell,
but is the model genuinely better, or did it just fit the noise in four houses?
→ Level 03, from Chapter 026.
🎥 See it before you study it — Neural
Networks,
3Blue1Brown. Its third and fourth videos are the clearest visual account of
gradient descent and backpropagation anywhere — the same loop you ran in §17,
drawn for a network with thousands of dials instead of two.
One channel, and how to use it
All three of those playlists come from
3Blue1Brown, which is Grant
Sanderson drawing mathematics instead of stating it.
There is a right and a wrong way to use it. The wrong way is to watch all three
series first and then come back — you will enjoy them and retain very little,
because nothing in you is yet asking the question each video answers. The right
way is the order this chapter has already put you in: hit the wall, then
watch.
You hit the first wall in §12, when nudging one dial at a time stopped scaling.
You hit the second every time this chapter said “we will justify that later”.
Each playlist above sits at the wall it belongs to. Watch it when you arrive
there, and it will feel less like new material than like someone finally
answering a question you were already carrying.
Why You Will Write Code, Not Only Read It
You can follow every line of this chapter without touching a computer. You
should still touch one — for three reasons that have nothing to do with jobs.
Python, because the loop is five lines and you will not believe it until you
run it.
Everything here — predict, measure, slope, step — is about five lines of
arithmetic inside a loop. Reading that it converges is one thing. Watching 41
become 28.45 become 0.0003 on your own screen, in code you typed, is another.
Then set η=0.13 and watch it fly apart, and you will never again wonder
whether the learning rate matters.
PyTorch, because it does the derivative you just did by hand.
We worked out ∂L/∂w=−35 on paper. PyTorch computes that for
any expression you can write, across millions of parameters — that is all
autograd is. Doing the hand calculation first is what turns autograd into a
labour-saving device instead of a magic box. And a tensor is just the vector
from Level 01 with a derivative attached.
Plots, because some things cannot be seen in a table.
The loss table read 30, 7.5, 1.875, 0, 1.875, 7.5, 30, and you had to take on
trust that this was a valley. Draw it and the valley is simply there. Draw the
η=0.13 run and you watch the swing widen. Draw a loss curve over training
and you can tell convergence from a plateau at a glance — a judgement you will
make every day, and one that numbers in a column do not give you.
You need none of this yet. Chapter 005 continues on paper. But when code
does arrive, it arrives as a way to check what you already understand — never
as a substitute for understanding it.
References
The two sources this chapter quotes directly.
Samuel’s checkers program
Samuel, A. L. (1959). “Some Studies in Machine Learning Using the Game of
Checkers.” IBM Journal of Research and Development, 3(3), 210–229.
https://doi.org/10.1147/rd.33.0210
Reprinted in the same journal in 2000, 44(1.2), 206–226 — which is why some
citations give those page numbers instead. Both refer to the same paper.
The definition of learning
Mitchell, T. M. (1997). Machine Learning. McGraw-Hill.
ISBN 978-0-07-042807-2.
The experience / task / performance definition quoted above opens Chapter 1,
on page 2.